Why Modern DAST Needs a Real Browser
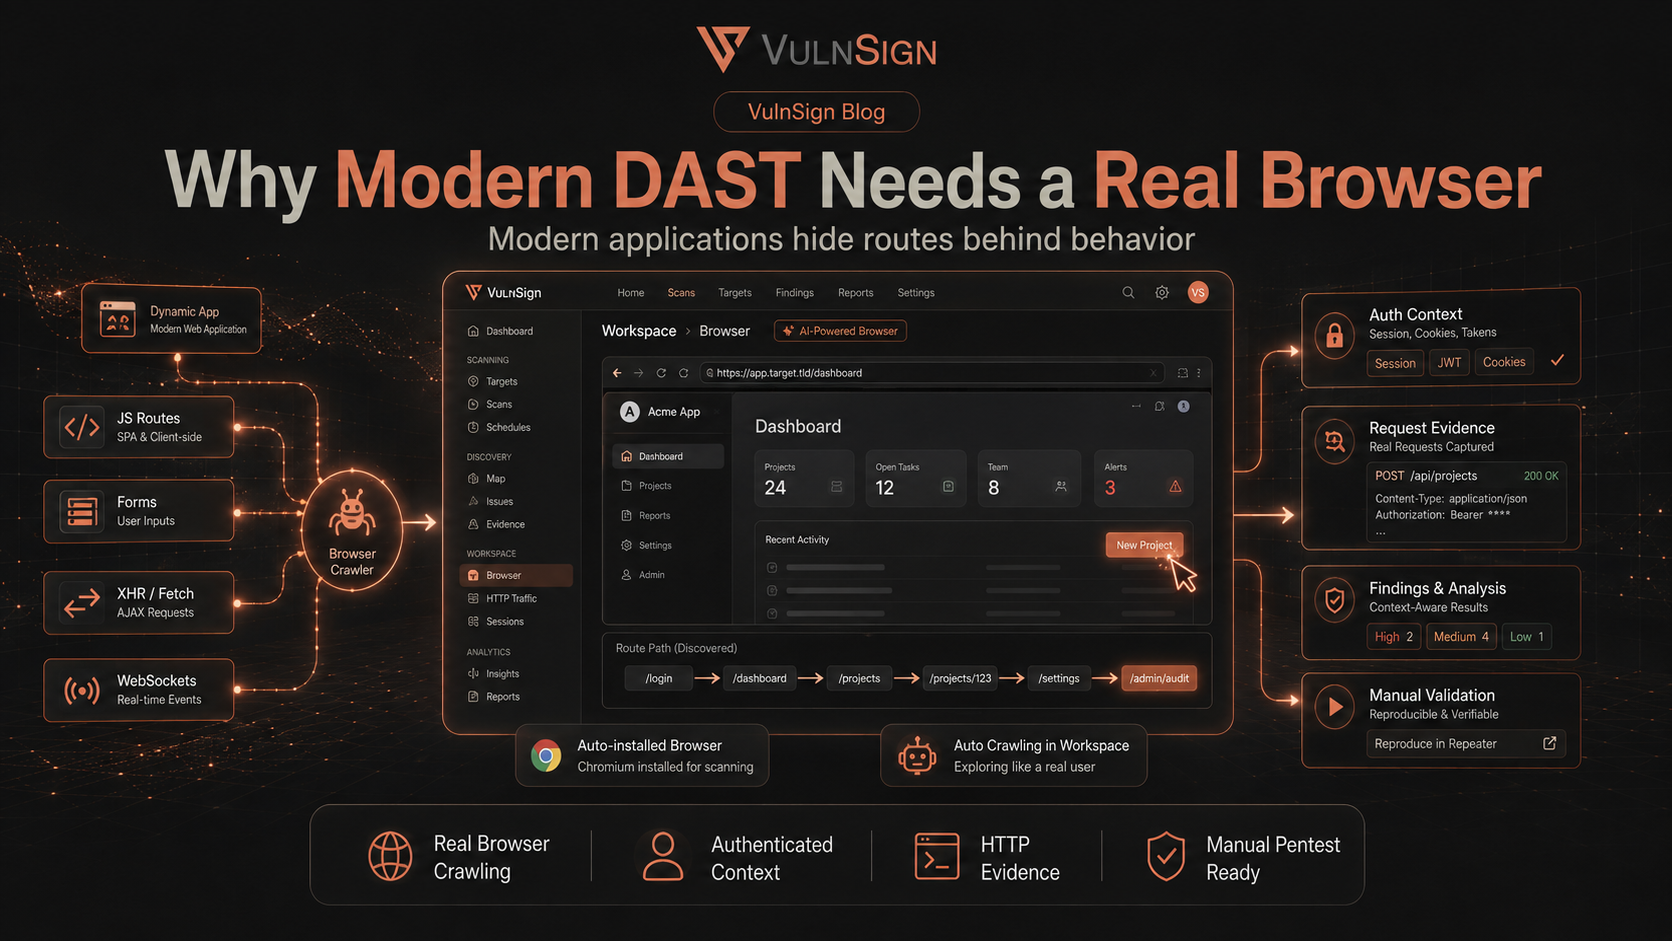
Modern applications hide routes behind behavior
A crawler that only follows HTML links can miss routes created by JavaScript, forms, XHR and fetch requests, WebSockets, client-side routing, and user events. A real-browser crawler executes the application and observes the dynamic surface a user can reach.
Discovery needs application context
Modern crawling is not simply rendering a page. The scanner must preserve cookies, local storage, browser history, and authentication state while controlling duplicate paths and unstable inputs. This context helps it reach authenticated workflows without turning every UI state into redundant scan work.
From browser events to testable requests
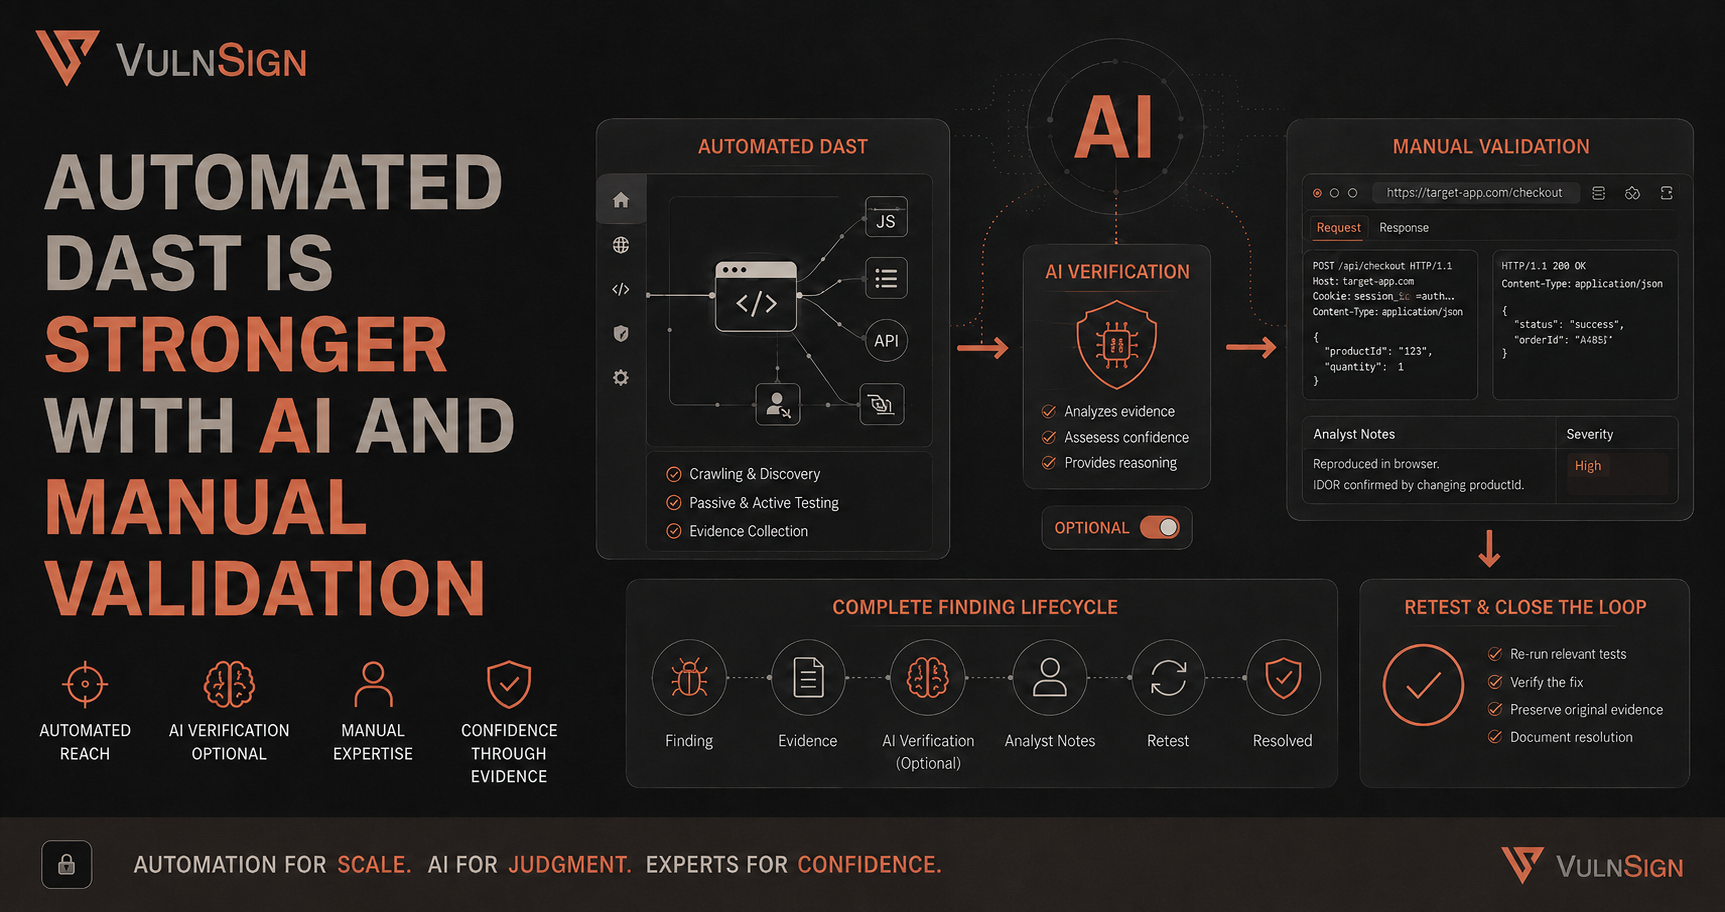
Useful discovery connects browser behavior to HTTP evidence. Requests observed during navigation become inputs for passive analysis, active testing, and manual validation. Security teams can then inspect the exact request and response behind a finding rather than treating the crawler as a black box.
What to validate in a DAST evaluation
Test the crawler against single-page navigation, multi-step forms, authenticated roles, API calls triggered by UI events, and logout/session renewal behavior. Coverage numbers matter only when discovered endpoints remain reproducible and safe to test.
Related Articles
Explore more insights, strategies, and perspectives related to this topic.
Questions before you scan?
Learn how VulnSign fits into your environment, security workflow, and team.
Put automated and manual testing in one workflow.
See how VulnSign helps your team discover more attack surface, validate risk, and move findings to remediation—without sending security data to a cloud control plane.